Yanjiu Conference logo

Call for Papers – ICVFMIU 2027, Phnom Penh

International Conference on Visual Foundation Models and Image Understanding — ICVFMIU 2027

Dates

11–12 January 2027

Venue

Phnom Penh, Cambodia

Field

Visual Foundation Models and Image Understanding

Topics of ICVFMIU 2027

Original papers are invited in Visual Foundation Models and Image Understanding. Submit by 10 December 2026.

Submit Your Paper

Topics include, but are not limited to:

Advancements in Visual Foundation Models

  • New architectures for visual learning tasks
  • Transfer learning in visual applications
  • Benchmarking datasets for model comparison
Image Understanding Techniques

  • Semantic segmentation innovations
  • Object detection methodologies
  • Challenges in image captioning

Interdisciplinary Applications of Image Analysis

  • Applications in healthcare imaging
  • Visual understanding in autonomous vehicles
  • Cultural heritage digitization projects

AI Ethics in Visual Technologies

  • Bias detection in visual algorithms
  • Privacy concerns with image data
  • Accountability in image analysis systems

Sustainability in Visual Model Development

  • Energy-efficient algorithm design
  • Impact of large models on resources
  • Sustainable practices in data collection

Future Directions in Image Processing

  • Integrating multimodal data approaches
  • Real-time processing challenges
  • Exploring human-computer interaction in visual tasks

Important Dates

Conference opens in

00days
00hours
00min
00sec
  1. Step 1

    Submission Deadline

  2. Step 2

    Registration Deadline

  3. Step 3

    Conference Date

Download

Get the official templates and forms for ICVFMIU 2027. Use the latest versions when preparing your submission.

Peer Review Process

Follow each step from abstract submission to awards and recognition.
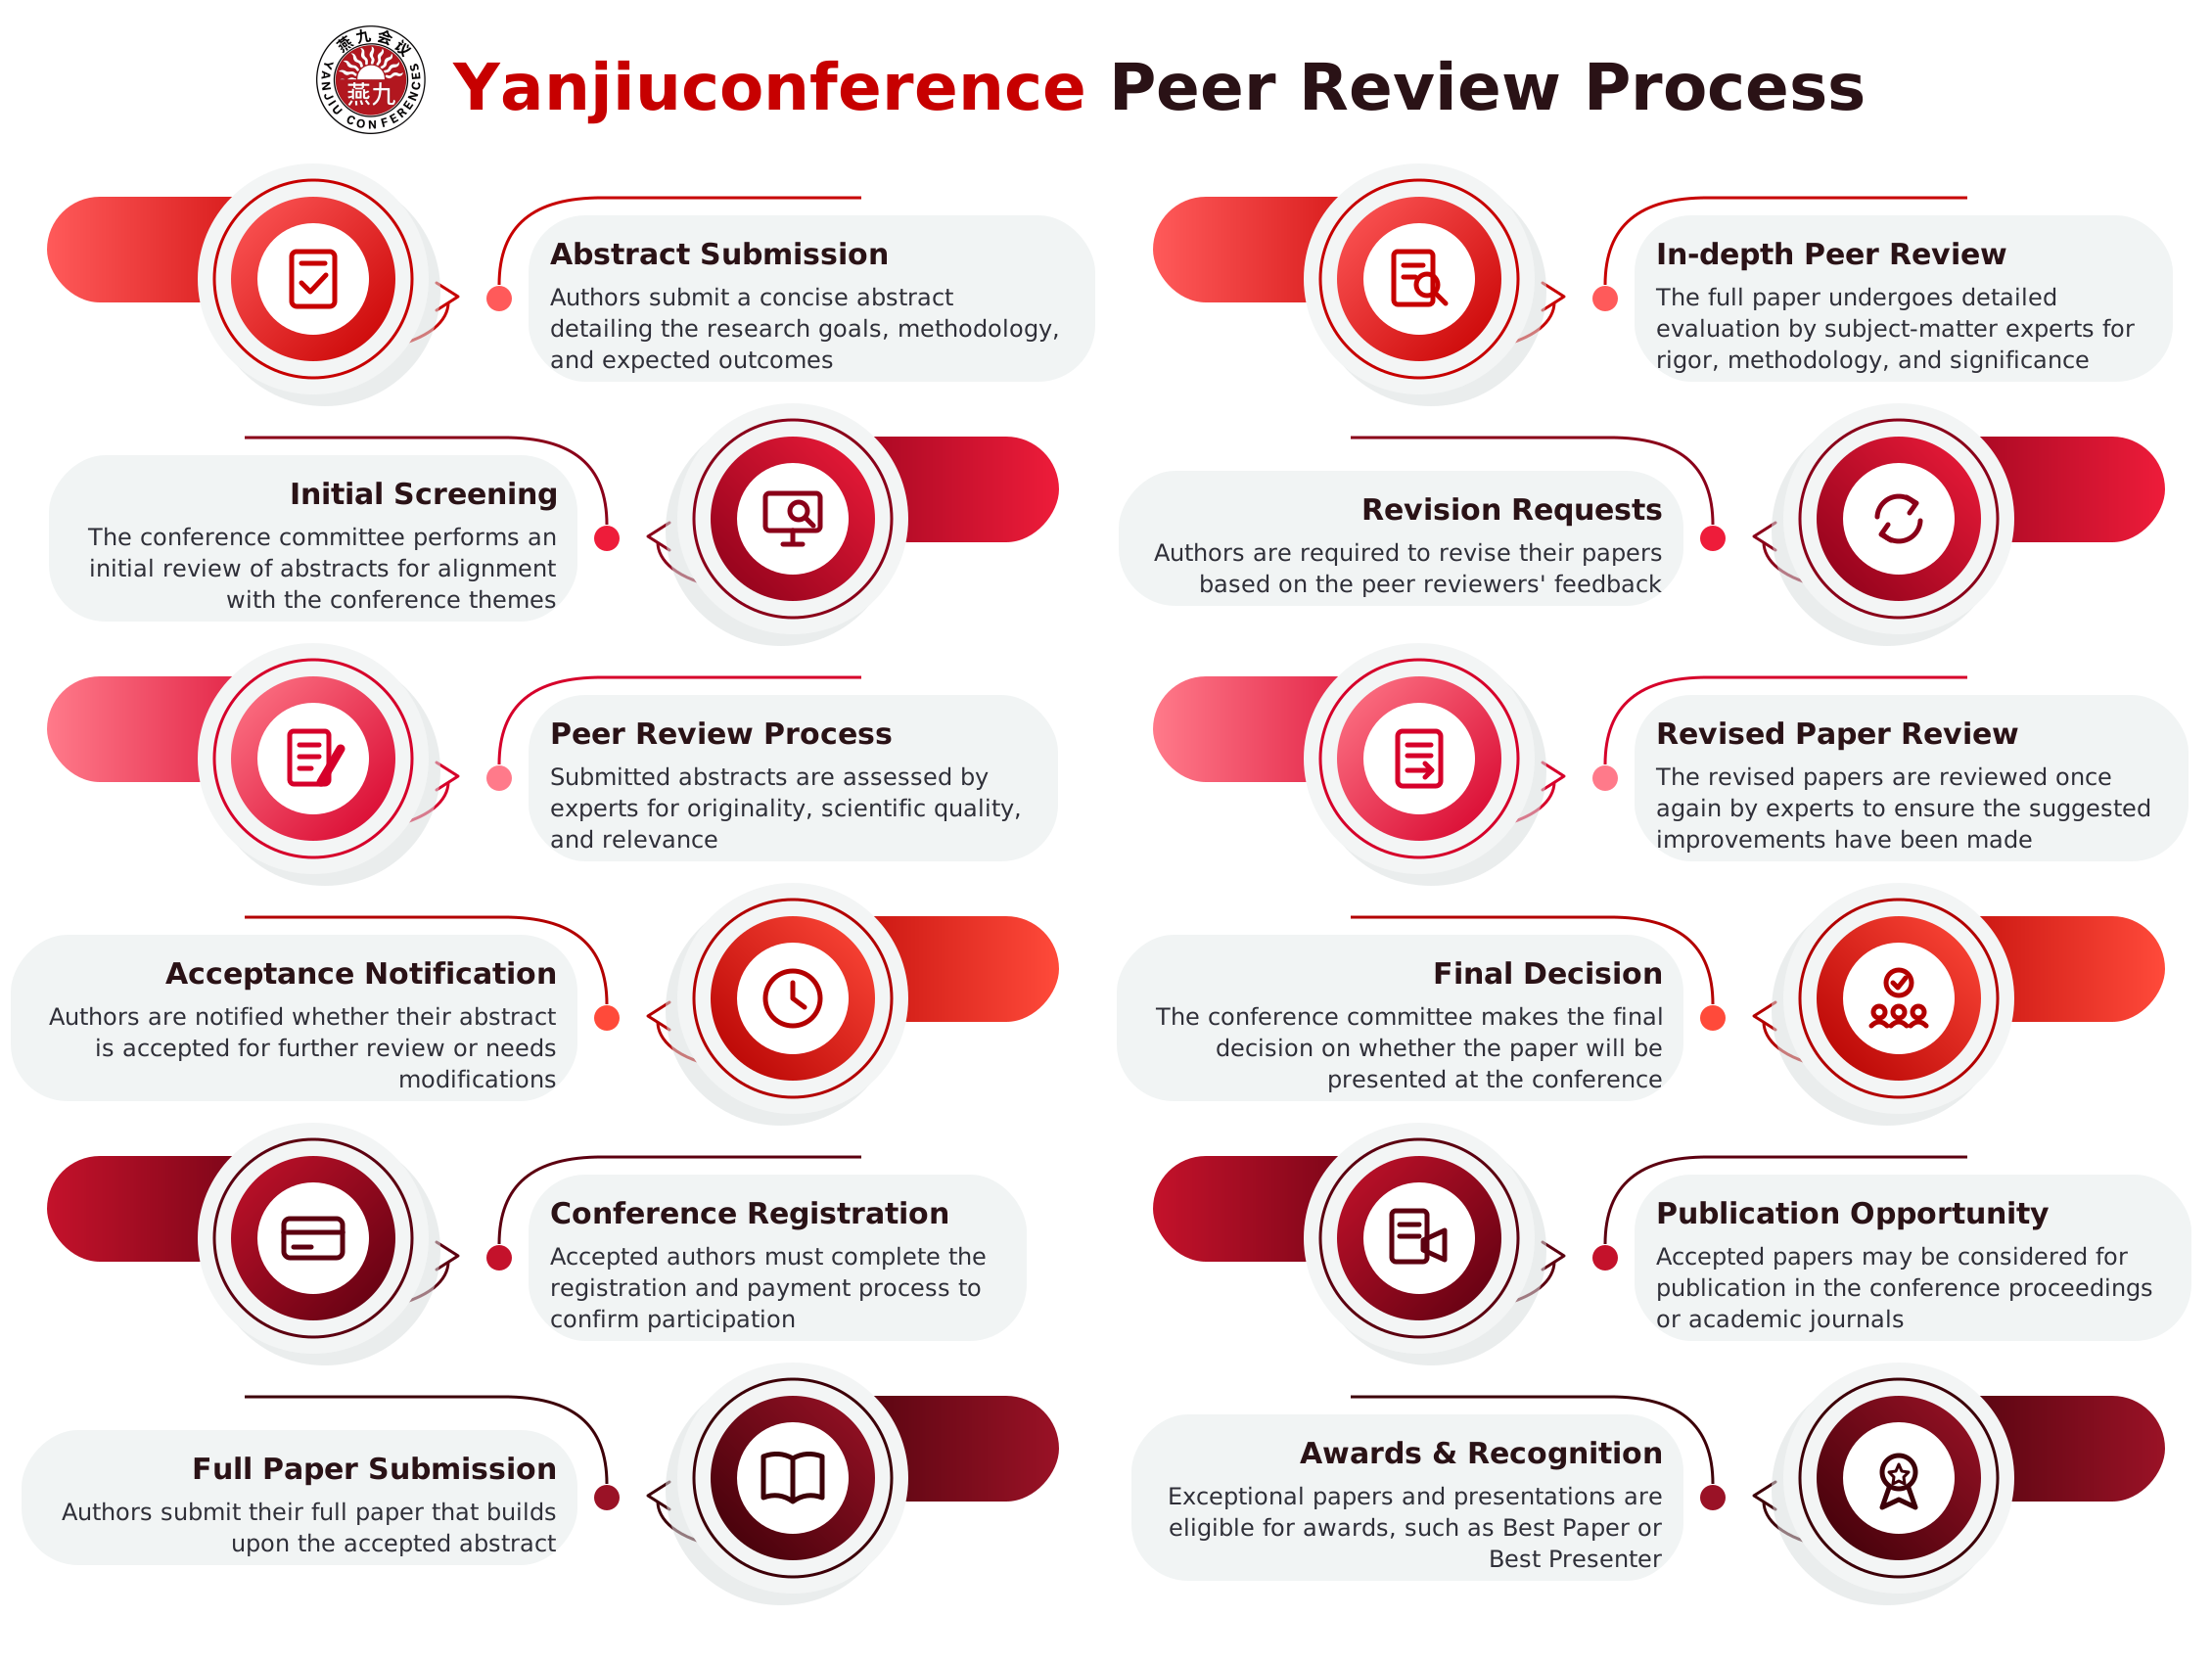
Yanjiuconference peer review process: 12 steps from abstract submission to awards and recognition

See You in Phnom Penh This January

Present your research, meet peers from over 50 countries and help shape the future of Visual Foundation Models and Image Understanding.